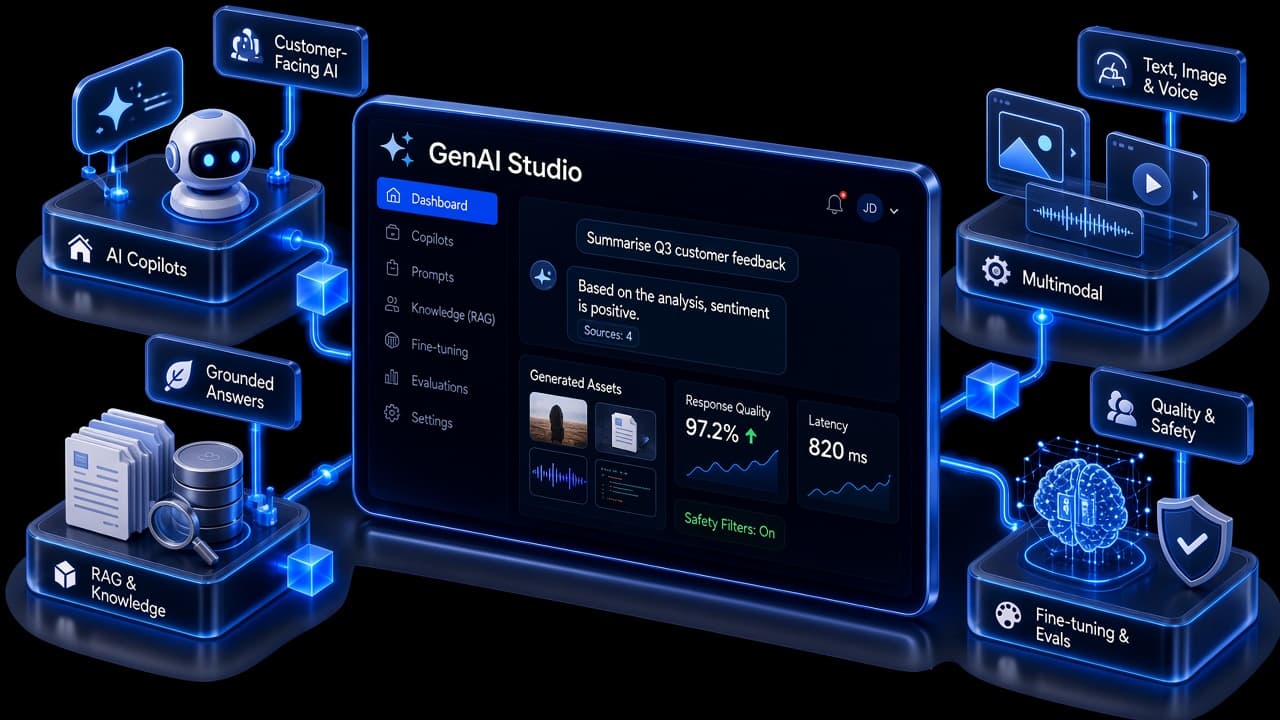
Generative AI studio dashboard connected to AI copilots, RAG knowledge bases, multimodal generation and fine-tuning with evaluations

Generative AISolutions

AI-native products your users will trust.

Production-grade AI-native products and customer-facing experiences - engineered with RAG architecture, fine-tuning programmes, multimodal pipelines and the evaluation rigour generative systems require.

Case Studies

Real Projects. Practical Solutions. Measurable Results.

Explore selected Bitronix builds across blockchain, AI, Web3 and digital assets production systems that turn requirements into reliable products.

  • DeFi Lending

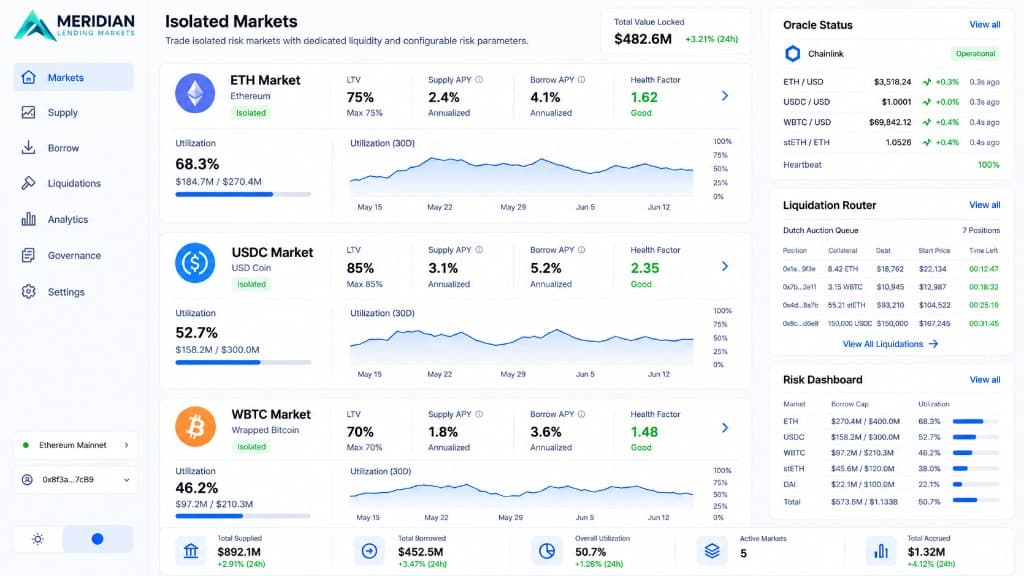
    Meridian

    Institutional-Grade DeFi Lending Protocol

    Meridian runs every lending market as an isolated pool with its own collateral rules and LTV limits, so a risky asset in one pool can never put deposits in another pool at risk.

    Lending Volume
    5M+
    Lending Pools
    50+
    On-Chain Transactions
    50K+
    Meridian product interface
    Read Case Study
  • Prediction Marketplace

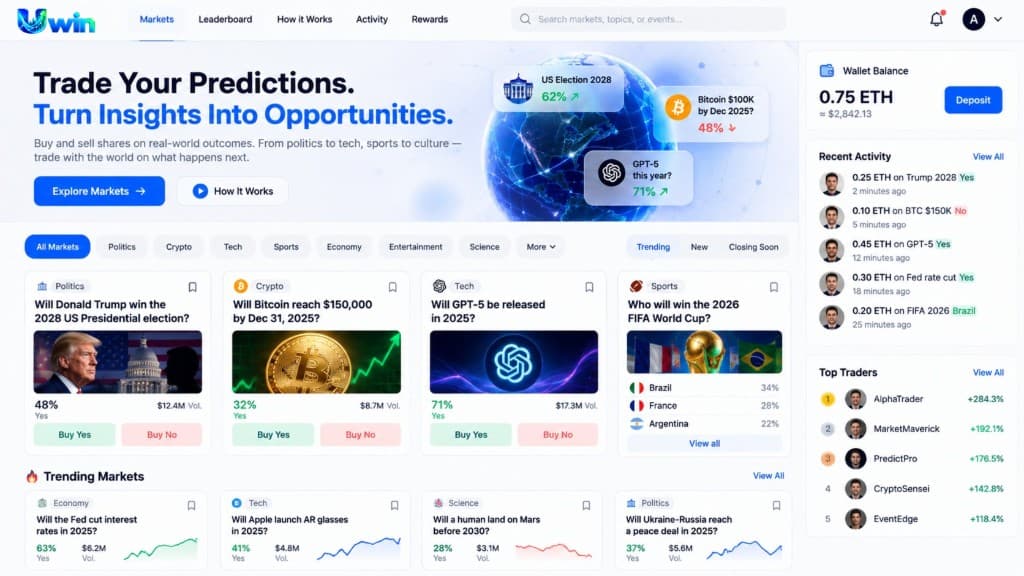
    Uwin

    A Polymarket-Style Prediction Marketplace

    Uwin is a prediction market where users buy YES or NO shares on real-world events. Smart contracts hold funds in escrow and pay winners automatically once the outcome is confirmed.

    Market Predictions
    10K+
    User Transactions
    25K+
    Settlement Accuracy
    99.9%
    Uwin product interface
    Read Case Study
  • Exchange

    NovaEx

    A Secure Multi-Asset Crypto Exchange

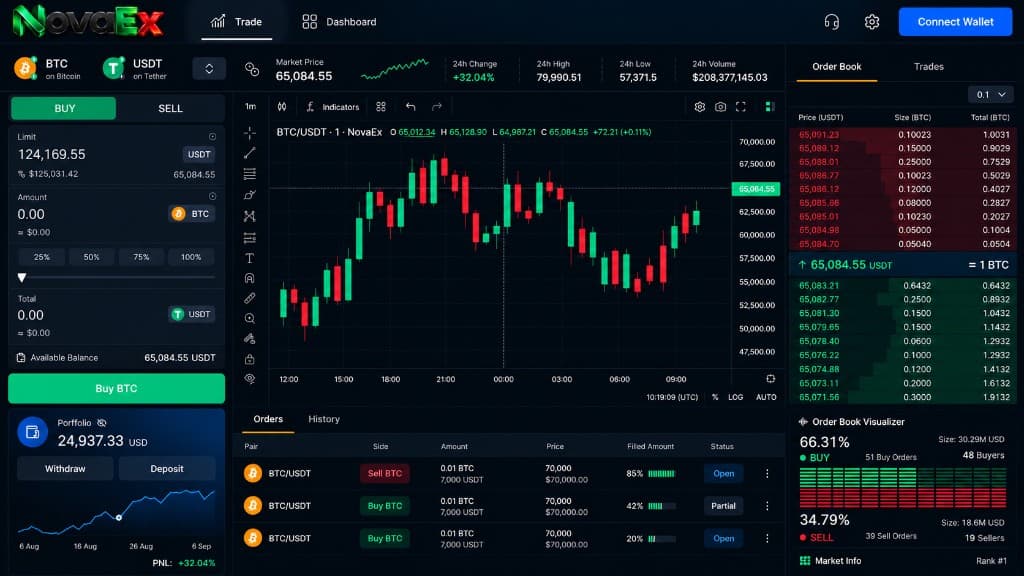
    NovaEx is a custom crypto exchange for spot trading across 100+ assets, with built-in wallet management, liquidity tools and live order books that stay responsive in busy markets.

    Trading Transactions
    1M+
    Supported Assets
    100+
    Active Traders
    50K+
    NovaEx product interface
    View Project
  • DeFi Exchange

    ProSwap

    A Uniswap-Style AMM DEX

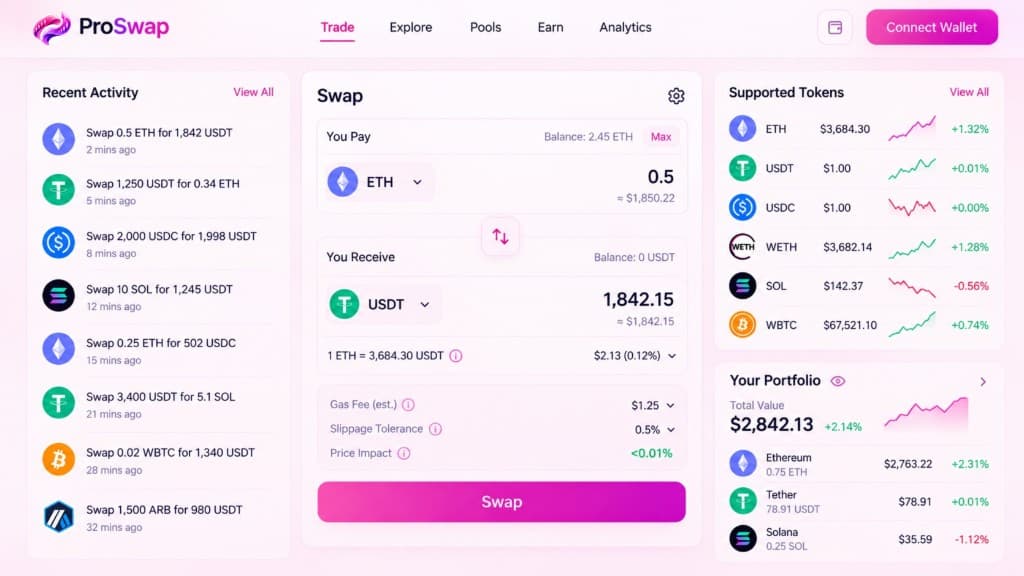
    ProSwap is an automated market maker DEX. Traders swap tokens straight from their wallets, liquidity providers earn a share of every trading fee and pool prices update on-chain.

    Active Traders
    5K+
    Trading Volume
    1M+
    Transactions Processed
    25K+
    ProSwap product interface
    Read Case Study
  • RWA Tokenization

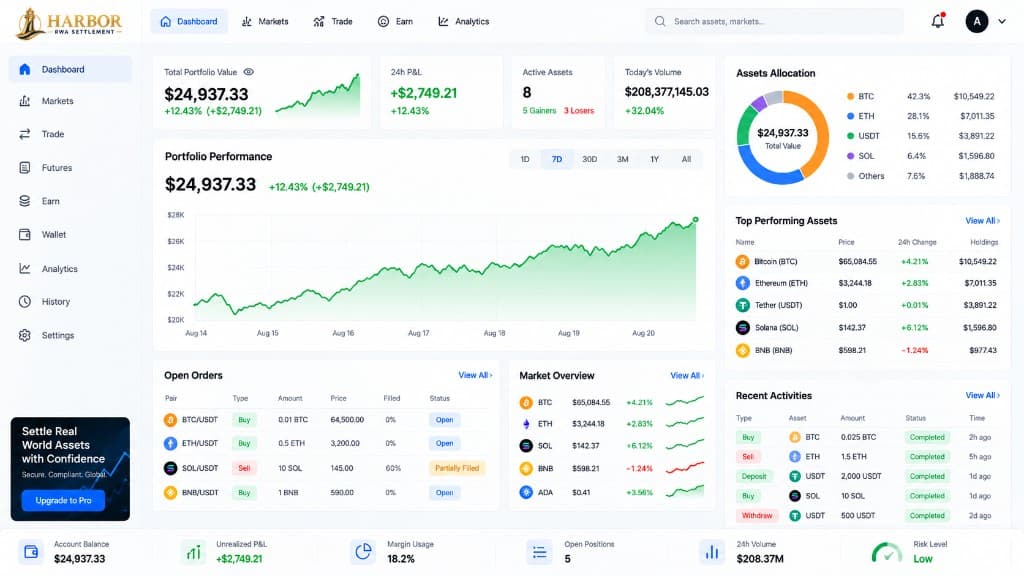
    Harbor

    On-Chain Settlement For Tokenized Real-World Assets

    Harbor settles tokenized real-world assets on-chain. Issuers mint tokens under set transfer rules, NAV oracles keep prices current and every subscription and redemption is tracked end to end.

    Asset Transactions
    $5M+
    On-Chain Settlements
    10K+
    Months Zero Breaks
    11+
    Harbor product interface
    Read Case Study
  • NFT Marketplace

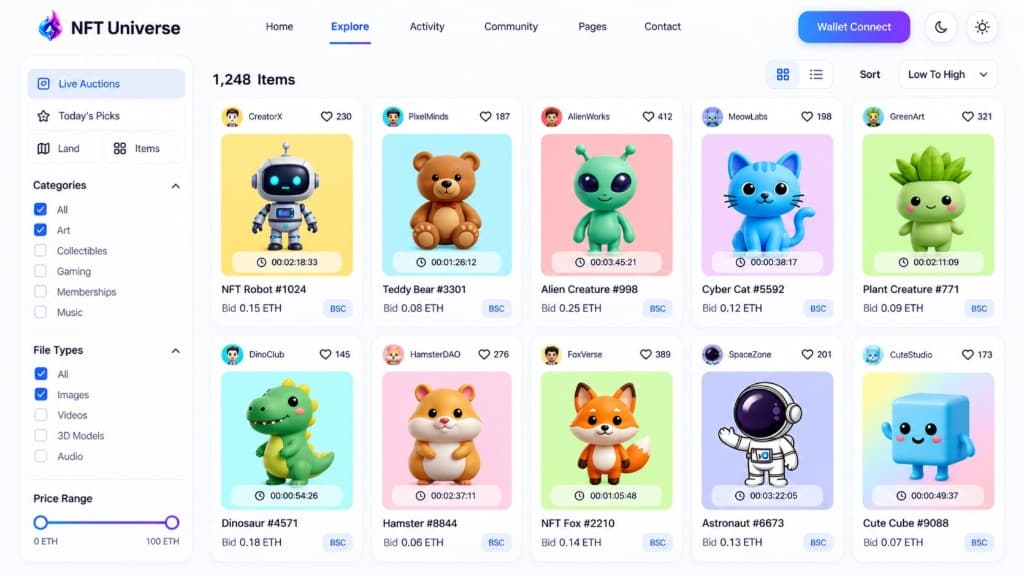
    NFT Universe

    An OpenSea-Class NFT Marketplace

    NFT Universe lets creators mint ERC-721 and ERC-1155 tokens, sell them at a fixed price or in timed auctions and earn royalties on every resale, with metadata stored on IPFS.

    Digital Assets
    10K+
    User Interactions
    50K+
    Trading Efficiency
    20X
    NFT Universe product interface
    Read Case Study
  • DeFi

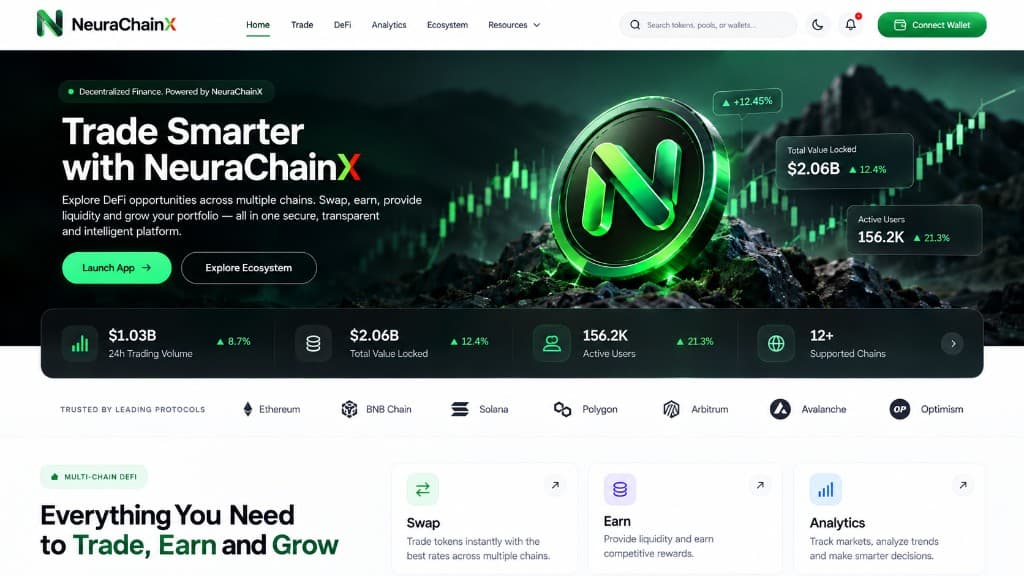
    NeuraChainX

    An AI-Powered Blockchain Ecosystem

    NeuraChainX puts AI market signals, multi-chain portfolio tracking and token swaps in a single dashboard, so traders can spot an opportunity and act on it without switching apps.

    Network Transactions
    100K+
    AI-Powered Use Cases
    50+
    Smart Contract Modules
    20+
    NeuraChainX product interface
    View Project

Our Services

Generative AI Services

Nine generative AI engineering disciplines - from RAG-powered products and fine-tuning programmes to multimodal pipelines, evaluation infrastructure and AI-native UX - each scoped independently and engineered to enterprise production standards.

Foundation and open-source model options including GPT-class models, Claude, Gemini, Llama, Mistral and fine-tuned small language models
  • AI-Native Product Engineering

    We build customer-facing products where AI is the core experience - co-pilots, generation tools, AI search, conversational interfaces - with streaming UX, error recovery and evaluation rigour designed in from day one.

  • RAG-Powered Applications

    We engineer retrieval-augmented generation products with hybrid search, reranking, citation grounding and faithfulness measurement - tuned against your actual users' queries, not generic benchmarks.

  • Fine-Tuning & Model Customisation

    We design fine-tuning programmes (supervised, DPO, RLHF) on Anthropic, OpenAI and open-source models - with evaluation harnesses that prove the fine-tune outperforms the base model on your specific tasks.

  • Multimodal Pipelines

    We build production systems that combine text, image, audio and document inputs - with model selection per modality, intelligent routing and unified observability across the pipeline.

  • Image & Video Generation Systems

    We deploy image and video generation infrastructure with content moderation, safety filtering, attribution tracking and rights-respecting workflows for brand-safe production use.

  • Voice & Conversational AI

    We engineer voice agents, real-time conversational systems and TTS/STT pipelines with low-latency streaming, interruption handling and emotion-aware response design.

  • AI Search & Discovery

    We build vector search, semantic ranking and AI-native discovery experiences - with hybrid retrieval, query understanding and grounded responses replacing legacy keyword search.

  • Code Generation & Developer Tools

    We engineer code-generation products, AI-powered IDEs and developer co-pilots - with code-aware evaluation, secure execution sandboxing and integration into existing developer workflows.

  • Evaluation & Quality Infrastructure

    We deploy LLM evaluation harnesses, golden datasets, A/B frameworks and continuous quality monitoring - so generative quality is measured rigorously across every model update, prompt change and retrieval modification.

  • 70+

    Generative AI products shipped to production

  • 240M+

    End-user generations served per month at peak

  • 25+

    Fine-tuning programmes deployed across model families

Delivery Scope

Six deliverables, zero ambiguity.

Every engagement produces a defined artifact set. Scope is agreed upfront; nothing is a billable surprise.

  • Deliverable 01

    Product definition & success metrics

    User experience scope, quality acceptance criteria, latency budgets and evaluation thresholds defined in coordination with your product team before architecture decisions.

  • Deliverable 02

    Model strategy & data audit

    Model selection (frontier API, fine-tuned, self-hosted), training data inventory, evaluation set construction and fine-tuning vs prompting decision documented with trade-offs.

  • Deliverable 03

    Evaluation harness & golden dataset

    Production-grade evaluation infrastructure with golden cases, regression detection, A/B framework and quality dashboards - built before the AI product itself.

  • Deliverable 04

    Production AI product

    RAG, generation, multimodal, or fine-tuned system deployed against the evaluation harness - with streaming UX, structured outputs where appropriate and observability instrumented from day one.

  • Deliverable 05

    Content safety & moderation pipeline

    Pre-generation and post-generation moderation, attribution tracking, abuse detection and human-review queues appropriate for your audience and regulatory context.

  • Deliverable 06

    Operational runbooks & quality monitoring

    Documented procedures for model migrations, prompt updates, fine-tune retraining cycles, content incidents and quality regression handling - handed to your product and ops teams.

Industries

Generative AI Across Industries

Nine industries where generative AI is creating new product categories, transforming customer-facing experiences and unlocking value from unstructured content.

  • Software & Developer Tools

    AI-powered IDEs, code-generation products, documentation assistants and developer co-pilots - engineered for code-aware evaluation, sandboxed execution and integration into existing developer workflows.

  • Media & Entertainment

    Content generation tools, AI-assisted editing, character generation and creator co-pilots - with brand-safety pipelines, attribution tracking and rights-respecting workflows for production use.

  • Education & Learning

    Personalised tutoring systems, AI-graded feedback, content generation for curricula and adaptive learning experiences - with safety guardrails appropriate for student users and regulatory compatibility.

  • Customer Experience & Support

    AI-native support products, conversational commerce, intelligent help centres and self-service co-pilots - with citation grounding and graceful escalation to human agents.

  • Financial Services

    Customer-facing financial co-pilots, advisory assistants, document-aware product experiences and AI-powered client portals - with compliance guardrails and audit trails for regulated environments.

  • Healthcare

    Patient-facing health information products, provider-facing clinical co-pilots and medical content generation - designed for HIPAA compatibility with safety boundaries on diagnostic and treatment guidance.

  • Legal

    AI-powered contract products, research co-pilots and legal document generation - engineered for citation accuracy and attorney-in-the-loop checkpoints on substantive legal output.

  • E-commerce & Retail

    AI shopping assistants, product discovery experiences, generative product imagery and personalised content engines - with brand-safety and inventory-aware grounding.

  • Web3 & Protocol Operations

    Governance summarisation tools, on-chain data co-pilots and protocol-native AI experiences - for protocol teams shipping AI products to their tokenholder communities.

Next Step

Ready to scope your generative AI product?

Share your use case, target users and success metrics - we respond within one business day with a scoped recommendation, not a sales pitch.

Book a Strategy Call

Why Bitronix

What Makes Bitronix Different

Not a feature list. Six specific reasons product leaders and engineering teams choose Bitronix for generative AI products that must hold up to user expectations, brand-safety reviews and the operational realities of probabilistic systems.

  • Evaluation-First Product Development

    We build the evaluation harness before the product. Golden datasets, A/B frameworks and regression detection exist on day one - so you ship with measurable quality, not subjective vibes. When a model provider ships an update or your prompt changes, you find out immediately whether quality moved up or down.

  • Streaming UX Engineering

    Generative AI products live or die on perceived latency. We engineer streaming responses, optimistic UI, partial-result rendering and graceful interruption - so the product feels fast even when the underlying model is slow. Free-text streaming with structured-output reconciliation isn't an afterthought; it's a core engineering discipline.

  • No Black-Box Development

    You see every architectural decision, every evaluation result and every failure mode as we build. Your product, brand-safety, legal and engineering teams get a live documentation trail they can review at any phase.

  • Model & Provider Agnostic

    We deploy across Anthropic, OpenAI, Google and self-hosted open models - and we know when to fine-tune versus when to prompt versus when to swap providers. The decision is driven by your users' latency, cost and quality requirements, not by which API we have a partnership with.

  • Brand-Safety & Content Moderation Aware

    Generative products that ship without content safety pipelines become PR incidents. We engineer pre-generation and post-generation moderation, abuse detection, attribution tracking and human-review queues - designed for your specific audience and regulatory context, not as an afterthought toggle.

  • A Track Record You Can Diligence

    Our case studies are public, our tech stacks are listed and our integrations are named. Read the architecture, check the evaluation methodology, verify the firms. We give you the evidence to decide, not asks to trust.

Client Testimonials

Hear Directly the Impact We've Createdfor Clients

Witness honest feedback from partners who built, launched and scaled their blockchain products with our experts.

5.0

10 Google reviews

Google

Really good experience with Bitronix Technologies. The team was professional, helpful and easy to communicate with. They understood my requirements and did a great job delivering the project. I really appreciated their attention to detail and willingness to help throughout the process. Would definitely recommend them!

Mohammad Haroon

a day ago · Google review

Google

We compared a few companies before choosing Bitronix and I think we made the right decision. The quality of work was good and the overall cost was reasonable. They were also flexible when we had some changes during development. Good technical team and good value for money.

Shivranjan Kumar

3 weeks ago · Google review

Google

I had a very good experience with Bitronix Technologies. Their team is very smart, helpful and knows their work well. They completed my project on time and the quality of work was really good. Thank you to the whole team for the hard work and support. I would surely recommend them.

Asif Ali

4 months ago · Google review

Google

My experience with Bitronix Technologies was excellent The staff were polite and professional, communication was clear and the project was completed on schedule. Their transparent pricing and smooth process made everything stress-free. Strongly recommend their services.

VISHAKHA CHAUDHARY

4 months ago · Google review

Google

Worked with Bitronix Technologies for a blockchain project and honestly couldn't be happier. They delivered everything on time, no delays, no excuses - and the pricing was very reasonable for the quality of work. The team clearly knows their stuff. Highly recommend if you're looking for reliable tech development!

Monty Thakur

4 months ago · Google review

Google

Had a great experience with Bitronix Technologies. They understood my requirements from the very first call. The process was smooth, communication was clear and the project was delivered on time. Pricing was fair and transparent with no hidden surprises. Highly recommended!

md empire

4 months ago · Google review

Google

A extremely brilliant experience. We are mesmerised by their services and the immense knowledge they have in their field. We certainly look forward to have a great relationship with this company and hope to do many projects together, learning and using their expertise for our business.

M محمد Riaz Vali Sayed

4 months ago · Google review

Google

Excellent service and communication, fast response and transparent , will do more business in future.

Asif Shahzad

4 months ago · Google review

Partner with us

Built for Teams Where AI Is the Product, Not a Feature.

Generative AI products fail when the model is treated as the differentiator. The model is a moving target - it gets cheaper, faster and better every quarter and your users don't care which one is behind your product. What they care about is whether the experience is fast, accurate, safe and consistent. We build for teams who treat the AI layer as engineering work - with evaluation harnesses, structured outputs where appropriate, content safety pipelines and the operational rigour that turns probabilistic systems into products customers trust.

Book a Strategy Call →

Engineering Methodology

How We Build Generative AI Products That Ship and Stay Shipped.

Most generative AI products fail not at launch but at week six - when prompt rot sets in, retrieval drifts against new content, model providers ship updates and quality regresses without anyone noticing. We engineer the preventable failures out so your AI product compounds value, not surprises.

Our methodology is available to review before you engage.

  • User Journey & Quality Bar Definition

    Before architecture decisions, we map the user journey, identify the moments of truth (first generation, complex query, edge-case input) and document the quality bar each moment must clear. Acceptance criteria are measurable - not "the AI should feel smart" but "responses must cite sources for 95% of factual claims with citation accuracy ≥ 92%."

  • Fine-Tune vs Prompt vs RAG Decision

    Each approach has costs, capabilities and failure modes. We document the trade-offs for your specific use case: prompting is fast but ceiling-bound, fine-tuning is capable but requires evaluation infrastructure, RAG is grounded but retrieval-quality-dependent. The decision is documented with rejected alternatives so your engineering team understands why the architecture is what it is.

  • Evaluation Harness Before Product Build

    Before the first prompt is written, we build the evaluation harness. Golden datasets are constructed from your real users' queries and your team's expert judgments. Quality metrics - accuracy, faithfulness, citation correctness, latency, cost, safety - are documented and automated.

  • Streaming UX & Latency Engineering

    Perceived latency drives generative AI product satisfaction more than absolute latency. We engineer time-to-first-token, partial-rendering strategies, optimistic UI and graceful interruption - so the product feels responsive at every model size and network condition.

  • Content Safety & Adversarial Testing

    Generative products are red-teamed against jailbreaks, prompt injections, brand-safety failures, PII exfiltration, copyright leakage and abusive use patterns. Failures are documented and bounded with guardrails before launch - not discovered when a journalist finds them.

  • Operational Handoff Pack

    Every engagement produces a structured handoff: documented prompts and rationale, evaluation harness with reproducible runs, observability dashboards, content moderation rules, runbooks for prompt updates and model migrations and a known-limitations document your support and product teams can reference under pressure.

Execution Model

Six Phases, One Accountability Chain.

No handoffs that lose context. The team that scopes your generative AI programme ships it and supports it post-launch. Every phase produces a defined artifact - nothing moves forward without it.

  1. Discovery & Product Definition

    Timeline: 1-2 weeks

    Product scope, target users, success metrics, latency budgets and content safety requirements mapped in coordination with your product team before model or architecture decisions.

    • Scope document with in/out boundaries
    • User journey specification
    • Quality bar definition
    • Content safety and regulatory constraint register
    • Engagement timeline with phase gates
  2. Architecture & Evaluation Design

    Timeline: 2-3 weeks

    System architecture, model strategy (fine-tune vs prompt vs RAG), evaluation harness, content moderation pipeline and integration topology documented. Golden dataset constructed.

    • Architecture specification
    • Model and approach selection rationale
    • Evaluation harness with golden dataset
    • Content safety pipeline design
    • Integration interface contracts
    • Observability plan
  3. Development

    Timeline: 3-12 weeks depending on scope

    Generative AI product, RAG pipelines, fine-tuning programmes, multimodal flows and integrations built against the evaluation harness - with continuous quality measurement and streaming UX validation in CI.

    • Production codebase with full documentation
    • Evaluation harness running in CI
    • Observability instrumented end-to-end
    • Content moderation pipeline live
    • Internal staging environment matching production
  4. Validation & Adversarial Testing

    Timeline: 2-4 weeks

    Red-teaming, jailbreak validation, brand-safety testing, latency and load testing and user-experience validation run before launch. Findings triaged and remediated against agreed severity SLAs.

    • Adversarial test suite with documented attack patterns
    • Jailbreak resilience report
    • Content safety validation report
    • Latency and load test results
    • Go/no-go checklist aligned to launch readiness
  5. Launch

    Timeline: 1-2 weeks

    Coordinated production deployment, observability go-live, content moderation activation, integration cutover and human-review queue configuration against explicit launch criteria.

    • Deployment record with reproducible builds
    • Observability dashboard go-live
    • Content moderation rule activation
    • Integration cutover log
    • Post-launch smoke and synthetic test reports
  6. Support

    Timeline: Ongoing - retainer or per-incident

    Quality monitoring, drift detection, prompt regression handling, fine-tune retraining cycles, model migration support and incident response under defined SLAs.

    • Quality and drift monitoring dashboard
    • Content safety incident playbook
    • Prompt-update and model-migration calendar
    • Monthly quality review (optional retainer tier)
    • Change request process for product extensions

Timelines assume responsive client feedback at phase gates. Data access provisioning, golden dataset curation and content safety policy alignment with brand and legal teams are typically the pacing items - programmes targeting a specific launch should engage Discovery 8-12 weeks before target deployment.

Tooling Stack

Our Generative AI Technology Stack

Chosen for production reliability, evaluation rigour and operational track record across enterprise generative AI deployments.

Default stack

  • Python
  • TypeScript
  • Anthropic SDK
  • Vercel AI SDK
  • Braintrust

01 / 04

Languages & frameworks

10 tools
  • Python

    AI development standard

  • TypeScript

    Production runtime

  • Vercel AI SDK

    Streaming UX

  • Next.js

    AI frontend framework

  • LangGraph

    Agent orchestration

  • LlamaIndex

    RAG framework

  • DSPy

    Prompt programming

  • Pydantic

    Structured outputs

  • FastAPI

    AI API framework

  • Modal

    Serverless GPU runtime

Trust & Diligence

AI Safety & Evaluation Partner Ecosystem

We coordinate AI safety review, content moderation evaluation and independent quality assessment with recognised firms your stakeholders, regulators and brand-safety teams already trust - a critical signal for production generative AI products serving end users at scale.

Third-party names and marks belong to their respective owners.

How we partner

Engagement Models

Three ways to engage - structured around how your team works, not how we prefer to sell. Every model operates on the same delivery standard, the same engineering team and the same accountability chain.

01

Dedicated Development Team

3-12 months · 2-5 engineers · Full-time exclusive

Your programme gets ML engineers, product-minded full-stack engineers and evaluation owners working exclusively on your generative AI product - suited to flagship customer-facing programmes, multimodal roadmaps and ongoing quality operations.

Best for: AI-native product roadmaps, regulated customer-facing experiences, continuous model and retrieval iteration

02

Team Extension

1-6 months · 1-3 engineers · Integrated with your team

We embed in your repos and design reviews - you retain product direction; we bring evaluation discipline, streaming UX patterns and production generative patterns your team is still ramping on.

Best for: Teams shipping a first generative customer experience, co-development with internal AI leads

03

Project-Based

4-16 weeks · Fixed deliverables · Fixed price

Defined scope before kickoff. AI feature builds within existing products, fine-tuning programmes, RAG stand-ups, evaluation harness deployments and adversarial review engagements are common formats - milestone gates and no billable surprises.

Best for: Targeted pilots, harness stand-ups, content-safety hardening, multimodal proofs of concept

Not sure which model fits? Book a 30-min scoping call → - we'll recommend the right structure based on your team, timeline and product scope.

FAQ

Frequently Asked Questions

Straight answers for product, engineering and procurement teams - before you enter diligence.

Next Step

Ready to ship a generative AI product your users will trust?

Share your use case, target users and launch window - we respond within one business day with a scoped recommendation.

Our offices

Direct lines to our delivery hubs. Same-day routing for qualified enterprise enquiries.

India

Global headquarters

Plot No 341, Industrial AreaPhase 9, MohaliPunjab 160066

Dubai

Middle East office

21st Floor, Court TowerBusiness BayDubai, UAE
SSL encryptedNDA on requestReply in 24hrs

No commitment required · NDA available on request · We respond within 1 business day